Desired-state contracts
This is the idea the whole product is built around, so it is worth understanding precisely rather than by analogy alone.
Desired vs actual, and who owns which
- The centre holds desired state. It is declarative, you describe the end state you want (a vSwitch with these adapters, a vNIC with this VLAN), never a sequence of steps. The centre never imperatively drives a host.
- The agent on each host continuously compares actual state (what the host is really configured as, read live) against desired state (what it was last told to enforce), and emits idempotent operations to close any gap.
- The agent also keeps a last-honoured copy of its desired state in a local embedded store. If the centre becomes unreachable, the agent does not stop or fall back to some default, it keeps enforcing exactly what it was last given, and reports itself as running autonomously.
This is what makes Ballast different from a centralised-only model: losing the centre never changes intent on a host, only the ability to change that intent.
What a declaration looks like
Every object Ballast manages has the same three parts:
meta: who it is.nameis required.labelsare free-form tags, and one is reserved:siteputs a cluster or host in a site.annotationshold notes and are kept in the centre only. The centre also setsuid,generationand the timestamps itself, so leave them out when you write.spec: what you declare. This is the contract.status: what the agent reports back. It is read-only, and ignored on write.
A cluster name is also a computer name in Active Directory, so it must be 15
characters or fewer and free of \ / : * ? " < > | , + = ; [ ]. A Replica Broker
name follows the same rule. Ballast refuses a name that breaks it, with the reason,
rather than let the role register under a truncated name that never resolves.
This section describes the 1.0.1 schema. The types themselves are the definition,
and they are public: see
api/types/desiredstate.go.
The smallest cluster
Three fields have no default and are what a cluster is: who is in it, the address it answers on, and how it keeps quorum. Everything else is optional.
{
  "meta": { "name": "WLGDC" },
  "spec": {
    "members": ["HVNEW01", "HVNEW02"],
    "managementIP": "192.168.1.200",
    "witness": { "type": "FileShare", "fileSharePath": "\\\\podman.ballast.local\\witness" }
  }
}
managementIP is a bare IPv4 address, not CIDR: it is handed to New-Cluster -StaticAddress. A witness is declared here and reconciled to, but the cluster
still owns every quorum decision. See
Witness configuration.
A full cluster on iSCSI
The same cluster with storage, a converged switch, live migration, a Replica Broker and an ISO library declared as well:
{
  "meta": {
    "name": "WLGDC",
    "labels": { "site": "Dev Site" },
    "annotations": { "notes": "Two-node lab cluster on iSCSI" }
  },
  "spec": {
    "members": ["HVNEW01", "HVNEW02"],
    "managementIP": "192.168.1.200",
    "witness": { "type": "FileShare", "fileSharePath": "\\\\podman.ballast.local\\witness" },
    "storage": {
      "kind": "iSCSI",
      "iscsi": {
        "portals": ["10.0.60.60", "10.0.61.60"],
        "targets": ["iqn.2026-09.local.ballast:primary"],
        "credentialSecret": "NewIscsi"
      }
    },
    "volumes": [
      { "name": "VMStorage", "source": { "serialNumber": "676a1462-835e-4387-9e42-e58e97973a01" } }
    ],
    "switches": [
      {
        "name": "Converged",
        "teamingMode": "SwitchIndependent",
        "loadBalancing": "Dynamic",
        "allowManagementOS": true,
        "hostNICs": {
          "HVNEW01": ["Ethernet 2", "Ethernet 3"],
          "HVNEW02": ["Ethernet 2", "Ethernet 3"]
        },
        "managementVNICs": [
          {
            "name": "Management",
            "hostIPs": { "HVNEW01": "192.168.1.201/24", "HVNEW02": "192.168.1.202/24" },
            "hostGateways": { "HVNEW01": "192.168.1.1", "HVNEW02": "192.168.1.1" },
            "hostDNS": { "HVNEW01": ["192.168.1.168"], "HVNEW02": ["192.168.1.168"] }
          },
          {
            "name": "LiveMigration",
            "purpose": "LiveMigration",
            "vlanID": 10,
            "minBandwidthWeight": 30,
            "hostIPs": { "HVNEW01": "10.0.10.11/24", "HVNEW02": "10.0.10.12/24" }
          }
        ]
      }
    ],
    "defaultStoragePath": "C:\\ClusterStorage\\VMStorage",
    "liveMigration": {
      "enabled": true,
      "authenticationType": "Kerberos",
      "maxConcurrent": 2,
      "networks": ["10.0.10.0/24"]
    },
    "replicaBroker": {
      "name": "WLGDC-Broker",
      "staticIP": "192.168.1.222",
      "storagePath": "C:\\ClusterStorage\\VMStorage\\Replica"
    },
    "isoLibrary": { "path": "\\\\podman.ballast.local\\isos", "credentialSecret": "IsoShare" }
  }
}
| Field | What it declares |
|---|---|
members | The host names that form the cluster. |
managementIP | The cluster's static management address. |
witness | type is FileShare, Cloud, Disk or None, with fileSharePath, cloudAccount or disk to match. |
storage | kind is S2D or iSCSI. Left out, it falls back to the older enableS2D flag, which is deprecated. |
volumes | The Cluster Shared Volumes. What one means depends on storage.kind, see below. |
switches | Cluster-wide SET switches. Each is created with the same name on every member, backed by that host's own NICs. |
defaultStoragePath | Where VM configuration and disks go by default on every member, typically a CSV. |
liveMigration | Live migration settings for every member. Left out, the centre applies enabled: true with Kerberos. |
replicaBroker | Provisions the Hyper-V Replica Broker role. name is required. |
isoLibrary | An SMB share every member reads boot media from. Declared once here and never copied into member hosts. |
A few things in that example worth knowing:
- Credentials are never in the JSON.
credentialSecretnames a credential stored in the vault. The declaration carries the name, and the secret stays sealed. switches[].hostNICsis per host, because adapter names belong to the machine and members do not have to agree on them. Every member needs an entry, or it never gets the switch.- A vNIC's addresses are per host too.
hostIPsvalues are CIDR (192.168.1.201/24). A host with no entry gets DHCP, so give every member an address on a vNIC its peers use. Ballast refuses to add a member that would otherwise join without one. purposesays what a vNIC carries: management (the default),Cluster,LiveMigrationorStorage.iscsi.portalsis required. With more than one portal, multipath I/O is required and cannot be switched off.
What a volume means depends on the storage kind
Ballast does not treat iSCSI as S2D with different field names, because the two models do not overlap. S2D pools local disks and Ballast decides size and resiliency. An iSCSI array owns both, so the cluster has no pool at all.
- Under iSCSI, a volume adopts a LUN the array already owns.
sourcenames it byserialNumber, or bytargetIQNandlun. Ballast does not create the LUN. - Under S2D, a volume is provisioned from the pool to the size you declare:
{
  "meta": { "name": "S2DDEMO" },
  "spec": {
    "members": ["HVNEW03", "HVNEW04"],
    "managementIP": "192.168.1.210",
    "witness": { "type": "FileShare", "fileSharePath": "\\\\podman.ballast.local\\witness2" },
    "storage": { "kind": "S2D" },
    "volumes": [
      { "name": "VMStorage", "sizeBytes": 1099511627776, "resiliencyType": "Mirror", "numberOfCopies": 2 }
    ],
    "defaultStoragePath": "C:\\ClusterStorage\\VMStorage"
  }
}
resiliencyType is Mirror or Parity, and numberOfCopies is the number of
data copies.
A standalone host
A host that is not in a cluster is declared the same way, with spec describing
that one machine:
{
  "meta": { "name": "HV01", "labels": { "site": "Branch Office" } },
  "spec": {
    "fqdn": "hv01.ballast.local",
    "enableHyperVRole": true,
    "rebootPolicy": "IfNeeded",
    "networking": {
      "dnsServers": ["192.168.1.168"],
      "switches": [
        {
          "name": "Converged",
          "teamMembers": ["Ethernet 2", "Ethernet 3"],
          "teamingMode": "SwitchIndependent",
          "loadBalancing": "Dynamic",
          "allowManagementOS": true
        }
      ],
      "managementVNICs": [
        {
          "name": "Management",
          "switchName": "Converged",
          "ipConfig": { "address": "192.168.1.31/24", "gateway": "192.168.1.1", "dnsServers": ["192.168.1.168"] }
        }
      ]
    },
    "storage": {
      "defaultVMPath": "D:\\VMs",
      "defaultVHDPath": "D:\\VMs\\Disks",
      "iscsi": {
        "portals": ["10.0.60.61"],
        "targets": ["iqn.2026-09.local.ballast:branch"],
        "credentialSecret": "NewIscsi"
      }
    }
  }
}
Most of what a cluster declares has a standalone form, and where it does, it is a
separate field with its own owner. The cluster's storage.iscsi and a host's
storage.iscsi are two fields, and Ballast refuses to let two objects claim the
same target, because two initiators logged in to one LUN each believe they own it
and a cluster cannot arbitrate against a host outside it. Point one of them at a
different target. clusterMembership is set by the centre when a host is made a
member of a cluster, so a standalone declaration leaves it out.
Some things have no standalone form at all, because they only mean something across hosts: failover, quorum and Cluster Shared Volumes.
Reading and writing it
The console's Desired state tab shows a cluster, host or VM wrapped in
"apiVersion": "ballast/v1" and "kind". Those two keys are added by the console
for display. They are not part of the API, and a request that includes them is
rejected, because the API refuses fields it does not know. Drop them if you copy
from that tab.
Over the REST API the same document is { "meta": ..., "spec": ... }:
| Request | What it does |
|---|---|
GET /api/v1/clusters/{name} | Returns the cluster, its status included. |
PUT /api/v1/clusters/{name} | Creates or replaces it. The name comes from the URL. A new cluster starts at generation 1, and each change to the spec adds one. |
GET /api/v1/clusters/{name}/history | The stored history of each generation. |
POST /api/v1/clusters/{name}/rollback/{generation} | Returns the spec to an earlier generation. |
Hosts are the same under /api/v1/hosts/{name}. Sign in with
POST /api/v1/auth/login and send the token as Authorization: Bearer <token>.
Writing needs the Operator or Administrator role.
TOKEN=$(curl -s --cacert ca.crt -X POST https://centre.example.com/api/v1/auth/login \
  -H 'Content-Type: application/json' \
  -d '{"username":"ops@example.com","password":"..."}' | jq -r .token)

curl -s --cacert ca.crt -X PUT https://centre.example.com/api/v1/clusters/WLGDC \
  -H "Authorization: Bearer $TOKEN" -H 'Content-Type: application/json' \
  --data @cluster.json
A PUT is a real change. The agents act on it as soon as they next pull, so treat
it the way you would treat editing the cluster by hand. Sending the same spec again
changes nothing: the generation only moves when the spec does, and any status you
include is discarded. Errors say what to fix: a
400 for a body or name that is not valid, a 409 when another object already
claims the storage, and a 403 with the code cluster_limit_reached when creating
another cluster would go beyond what your licence covers.
Generation and ObservedGeneration
Every desired-state object carries a Generation, incremented by the
centre each time it changes. The agent reports back
Status.ObservedGeneration, the generation it has actually reconciled
actual state to.
Generation == ObservedGeneration, settled; the host matches what was asked of it.Generation > ObservedGeneration, a change is outstanding; the host has not yet caught up, whether because it is mid-reconcile or because it is offline from the centre and reconciling against an older cached copy.
The console's drift indicator is built directly from this pair, not from a generic health check:
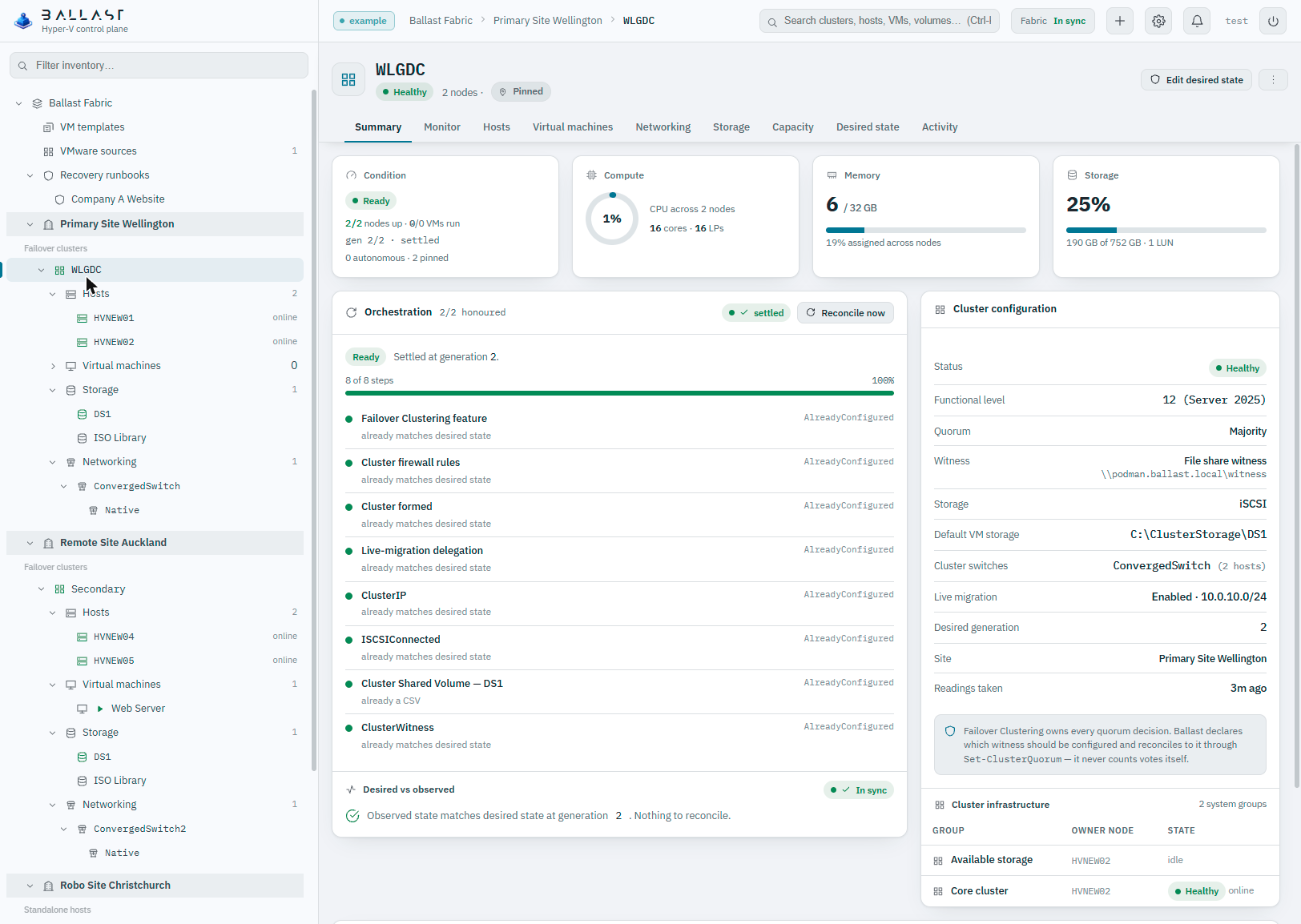
Every step is individually named and its own outcome shown, AlreadyConfigured
for a no-op pass, Updated for one that changed something this pass (here,
ISCSIConnected had to be adjusted), rather than one pass/fail rollup for
the whole object.
Drift detection
Drift is any difference between what the agent finds on the host and what its current desired state says should be there, someone changing a vSwitch by hand in Hyper-V Manager, for instance. The agent detects this on every reconcile pass.
Auto-revert vs approval-gated
Not every drifted field is corrected the same way. Every resource type falls into one of three tiers:
- Locked, cluster configuration and membership itself. Not reconfigurable through drift handling at all: no auto-revert, no approval flow. Changes to cluster topology only happen through the centre directly. This is the highest blast-radius category (split-brain, quorum loss, stranded VMs), so it gets no autonomous path whatsoever.
- Additions, net-new, additive changes, like a new virtual switch or a new VLAN. Low risk, since they don't affect anything already working: these are flagged/notified to the admin but applied without waiting for approval, so ordinary day-to-day operations (a new project needs a VLAN) don't require a gate.
- Modifications, anything that touches existing, currently-working configuration: VM specs (CPU, memory), disks, and witness configuration. The default posture is to not touch what's already working without asking first. The agent detects the drift, notifies the admin through the centre, and waits for an explicit approve or reject before applying it. Validation runs as part of applying an approved change, and a failed validation leaves the previous working configuration untouched. Everything not in the first two tiers auto-reverts to the desired-state contract on drift; this tier is the deliberate exception because the cost of a wrong auto-revert (or a wrong auto-apply) is high enough to warrant a human in the loop.
Witness configuration changes get an extra safeguard: because a broken witness is a silent failure mode (no symptoms until an actual node failure), approving a witness change tests both the old and the new witness, not just the new one, which can also surface that the current witness is already broken, independently of the change being reviewed.
Idempotency, non-negotiably
Applying the same desired state twice must always be a no-op. Every reconciler is written and tested to this rule; it is what makes the reconcile loop safe to run continuously rather than only on a triggered change.